1Zhejiang University 2The Hong Kong Polytechnic University 3IROOTECH & Wolf 1069 b Lab, Sany Group 4Institute of Computing Technology, CAS 5King's College London
*Equal contribution †Corresponding author
TL;DR
LMR turns text-to-motion generation into think, then act: an autoregressive model first generates a short sequence of reasoning tokens that plans the motion in a learned, motion-aligned latent space, then generates full-rate execution tokens conditioned on that plan.
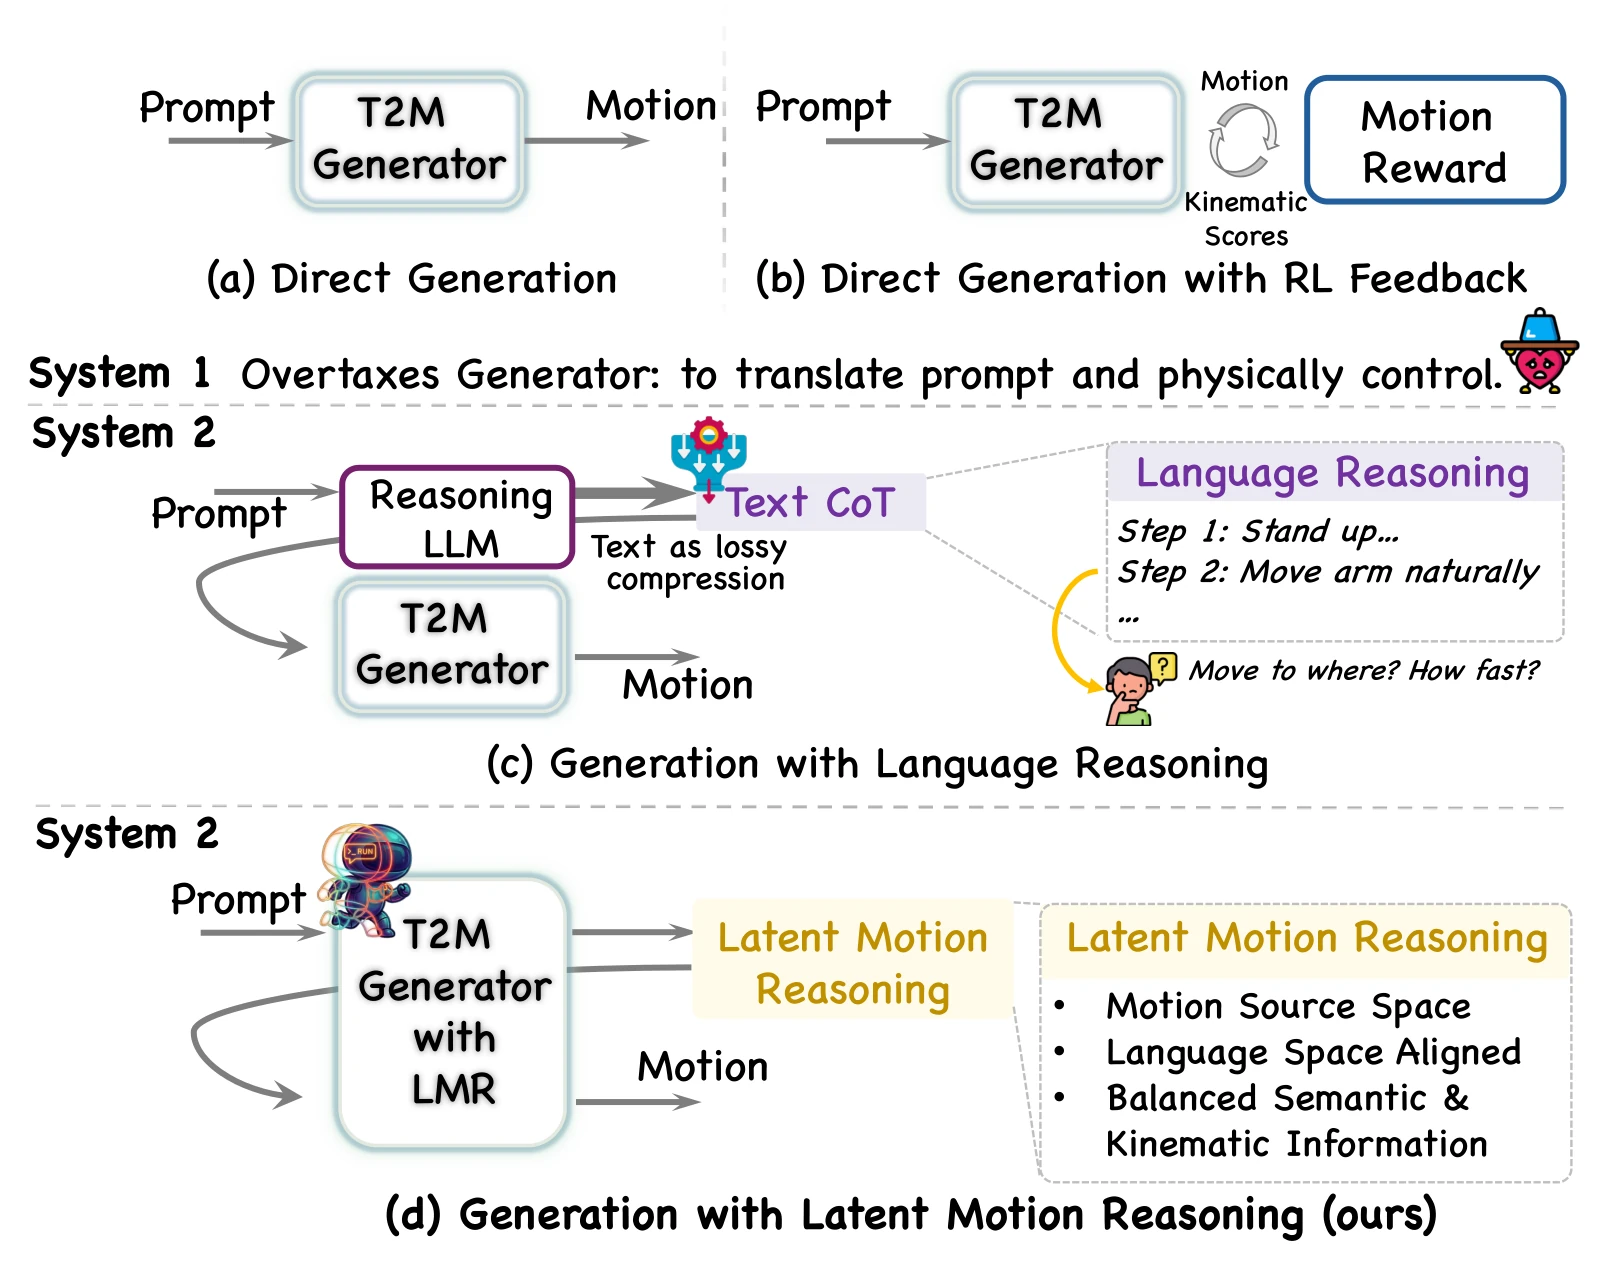
Current state-of-the-art paradigms predominantly treat Text-to-Motion (T2M) generation as a direct translation problem, mapping symbolic language directly to continuous poses. While effective for simple actions, this “System 1” approach faces a fundamental theoretical bottleneck we identify as the Semantic-Kinematic Impedance Mismatch: the inherent difficulty of grounding semantically dense, discrete linguistic intent into kinematically dense, high-frequency motion data in a single shot. In this paper, we argue that the solution lies in an architectural shift towards Latent System 2 Reasoning. Drawing inspiration from Hierarchical Motor Control in cognitive science, we propose Latent Motion Reasoning (LMR) that reformulates generation as a two-stage “Think-then-Act” decision process.
Central to LMR is a novel Dual-Granularity Tokenizer that disentangles motion into two distinct manifolds: a compressed, semantically rich Reasoning Latent for planning global topology, and a high-frequency Execution Latent for preserving physical fidelity. By forcing the model to autoregressively “reason” (plan the coarse trajectory) before it “moves” (instantiates the frames), we effectively bridge the ineffability gap between language and physics. We demonstrate LMR's versatility by implementing it for two representative baselines: T2M-GPT (discrete) and MotionStreamer (continuous). Extensive experiments show that LMR yields non-trivial improvements in both semantic alignment and physical plausibility, validating that the optimal substrate for motion planning is not natural language, but a learned, motion-aligned concept space.
Motivation
Most text-to-motion models translate a sentence straight into poses. This single-shot, “System 1” mapping has to plan the global trajectory and guarantee local physical fidelity at the same time. The paper calls this the Semantic-Kinematic Impedance Mismatch: language is discrete and semantically dense, motion is continuous and kinematically dense.
An explicit language chain-of-thought, as in Motion-R1, adds a planning step, but text is a lossy compression of kinematics. A weight shift or the damping of a joint is hard to put into words, yet it is distinct in a vector space. Reasoning in language limits planning to language fluency rather than physical validity.
LMR plans in a latent space that is aligned with language but grounded in motion, and only then generates frames.
Analysis
Before building LMR, we probed what makes a good latent substrate for planning. Two properties of motion tokenizers turn out to matter.
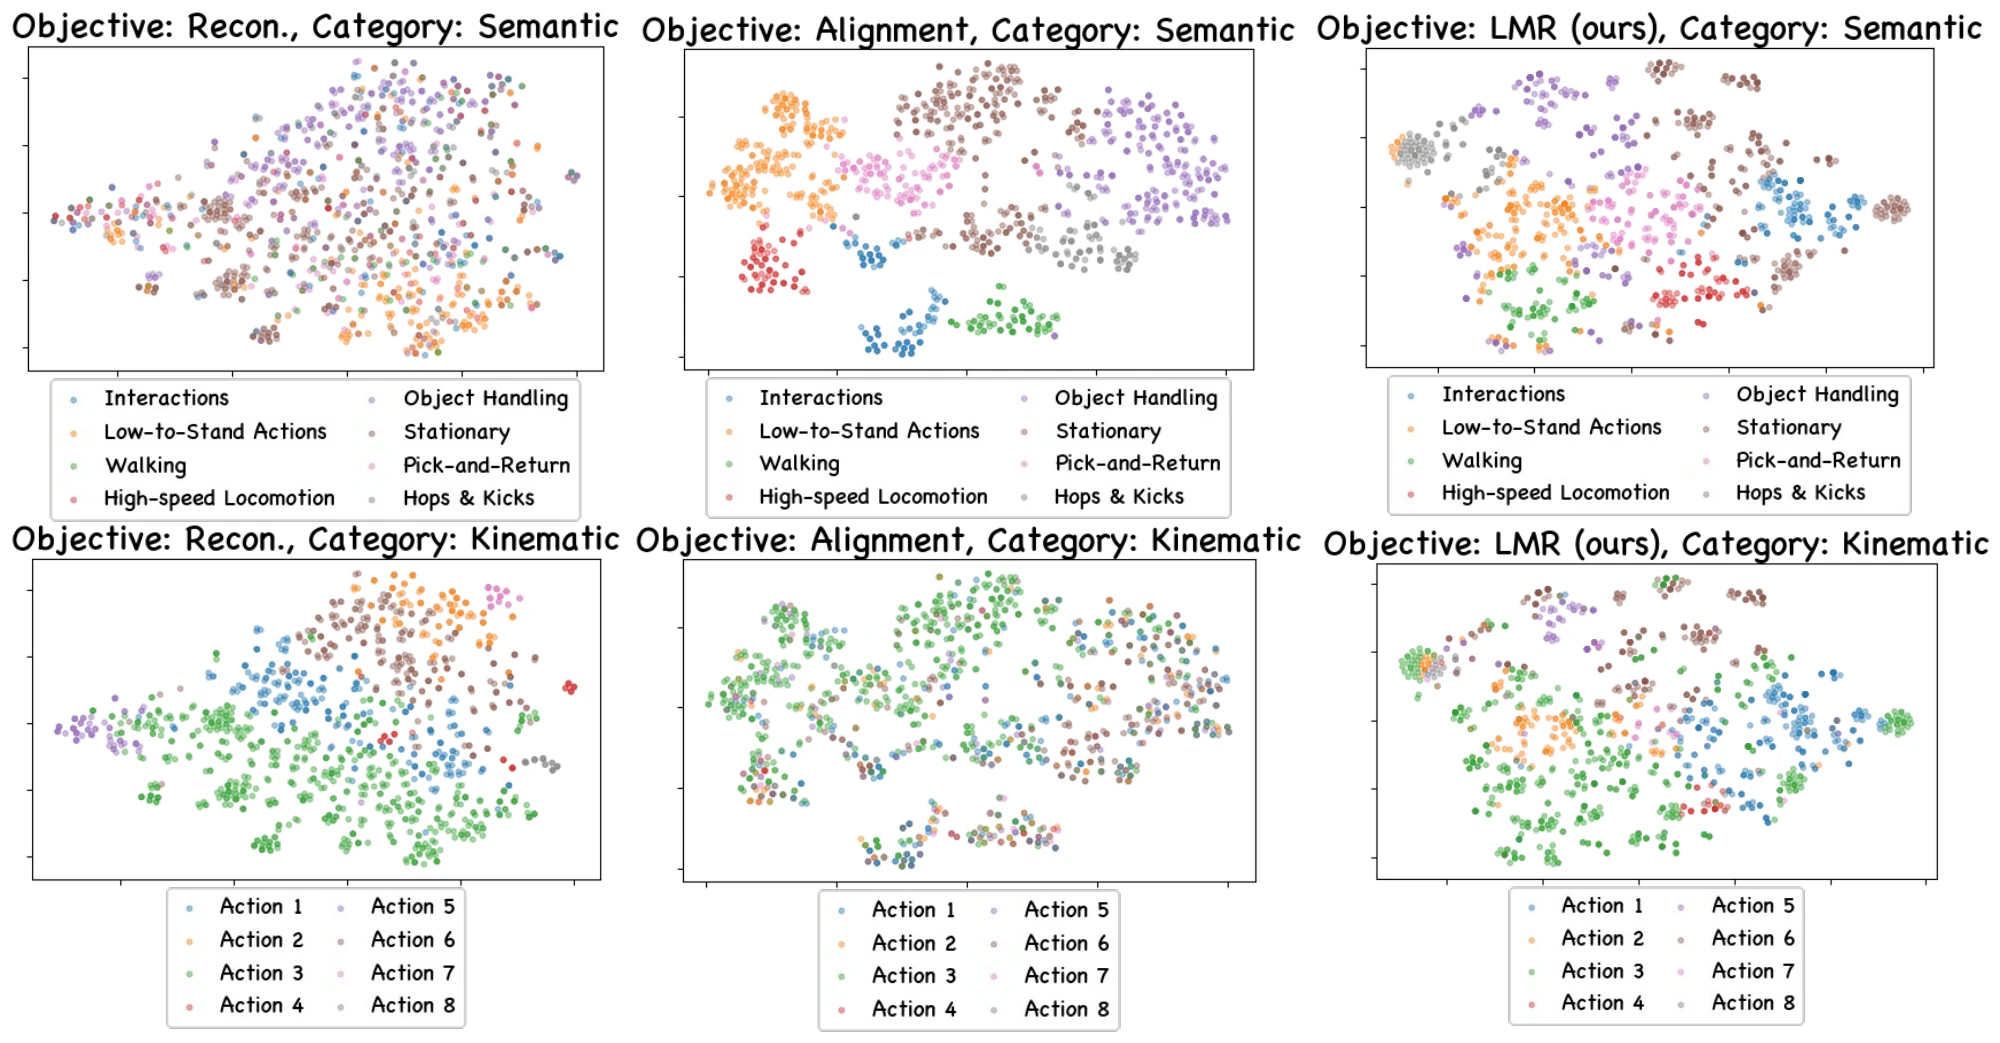
We tokenize the same HumanML3D motions with a reconstruction objective and with a text-alignment objective, then color t-SNE projections by semantic category (top row) and by kinematic action (bottom row). Reconstruction clusters kinematics but entangles semantics; alignment separates semantics but blurs kinematics. A single latent cannot hold both, so LMR disentangles planning and execution into two manifolds on a shared encoder (right column).
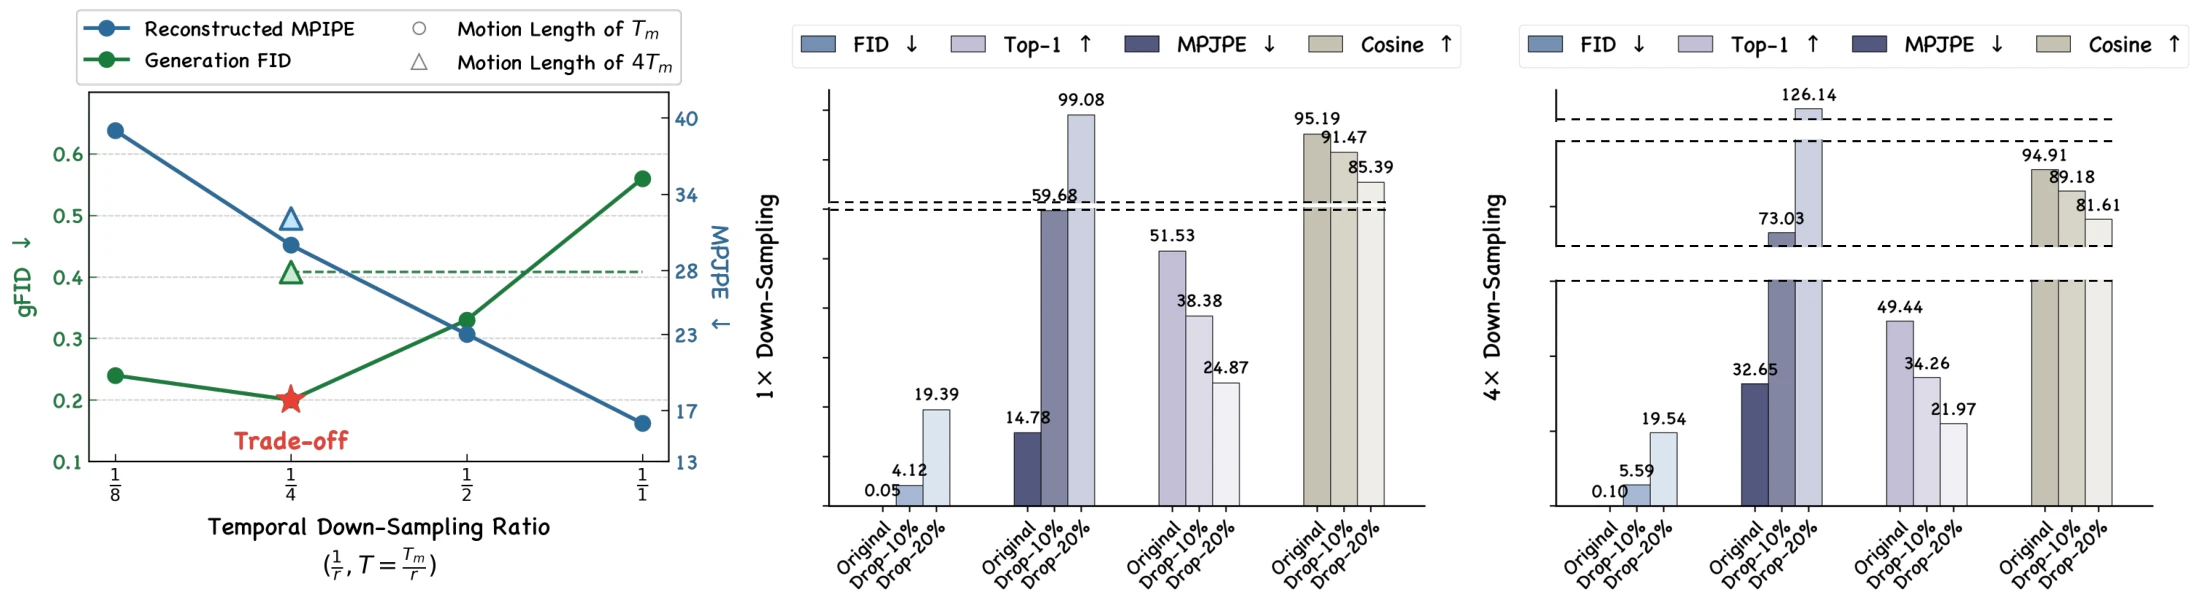
Reconstruction error keeps falling as tokens get denser, but generation FID is best at 1/4 temporal compression (left). At the same token count, a 4×-compressed long sequence generates better motion than an uncompressed short one. Randomly dropping tokens hurts the uncompressed sequence less (middle vs. right), because its semantics are spread thin across many frames. LMR therefore plans with a T/4 reasoning sequence and executes at full frame rate.
Method
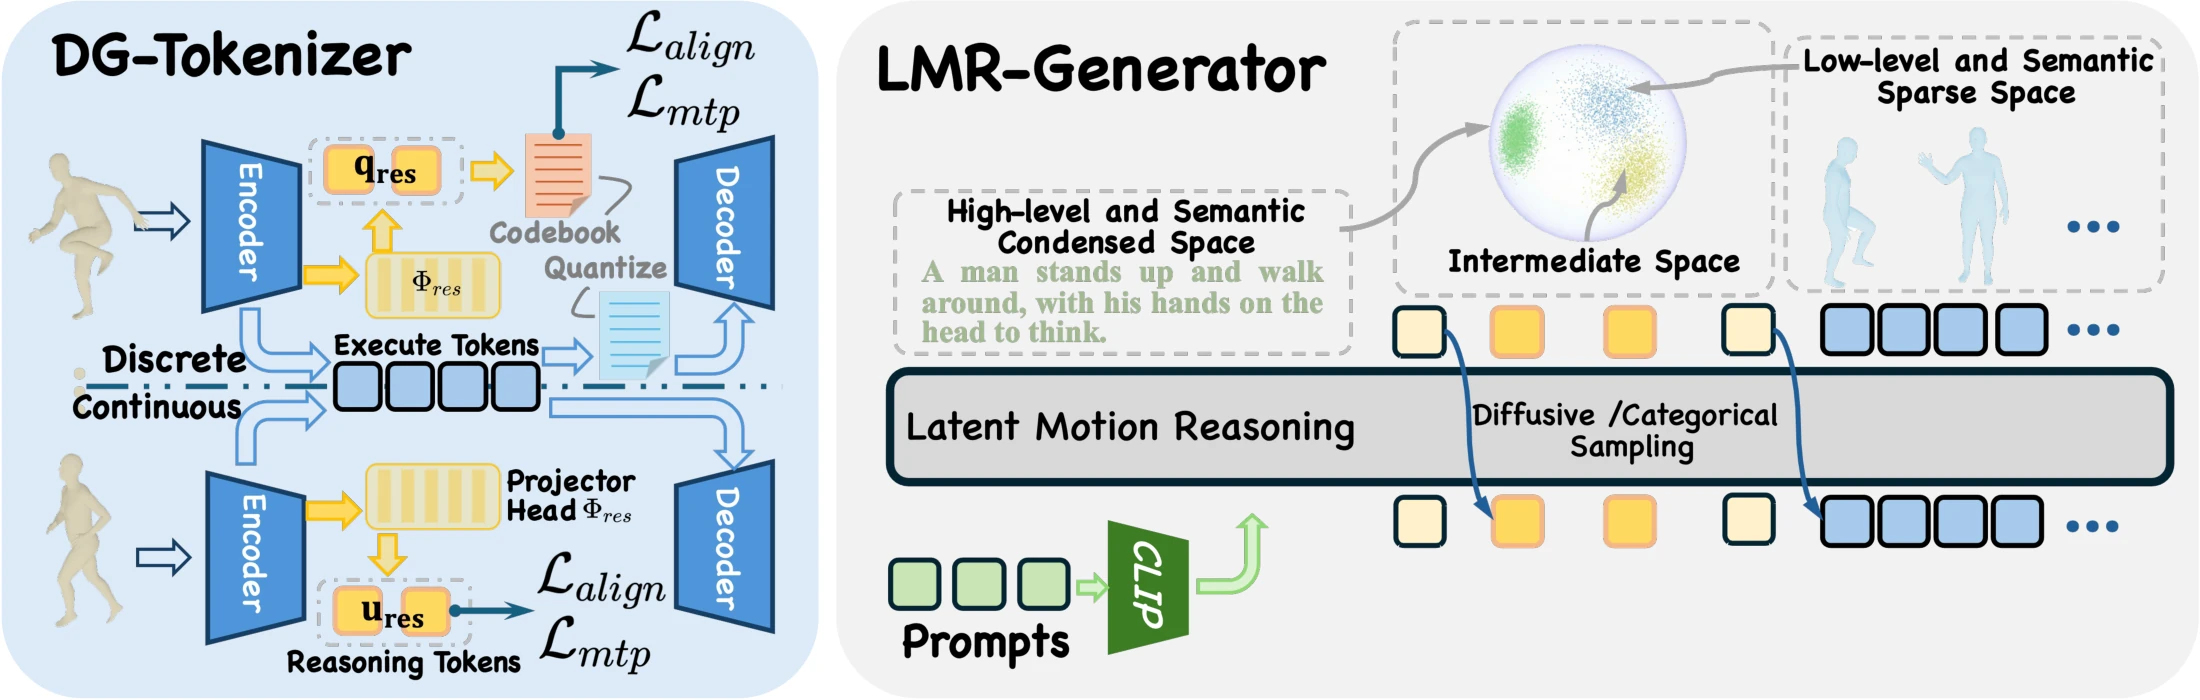
LMR factorizes generation into a two-stage causal chain: first a compressed, semantically dense reasoning sequence, then a high-frequency execution sequence conditioned on it.
A shared encoder feeds two branches. The execution branch keeps the full frame rate and is trained for reconstruction. The reasoning branch is compressed to T/4 and trained with a global text-alignment loss (Lalign) and masked text prediction (Lmtp), so its tokens carry verbs, body parts and directions.
One autoregressive Transformer generates the T/4 reasoning tokens first and the T execution tokens second. During execution it attends back to the finished plan, so the global topology is fixed before any frame is produced.
On T2M-GPT, LMR uses dual codebooks and a switching prediction head trained with cross-entropy. On MotionStreamer, it uses dual projections and per-token diffusion. The recipe is the same in both.
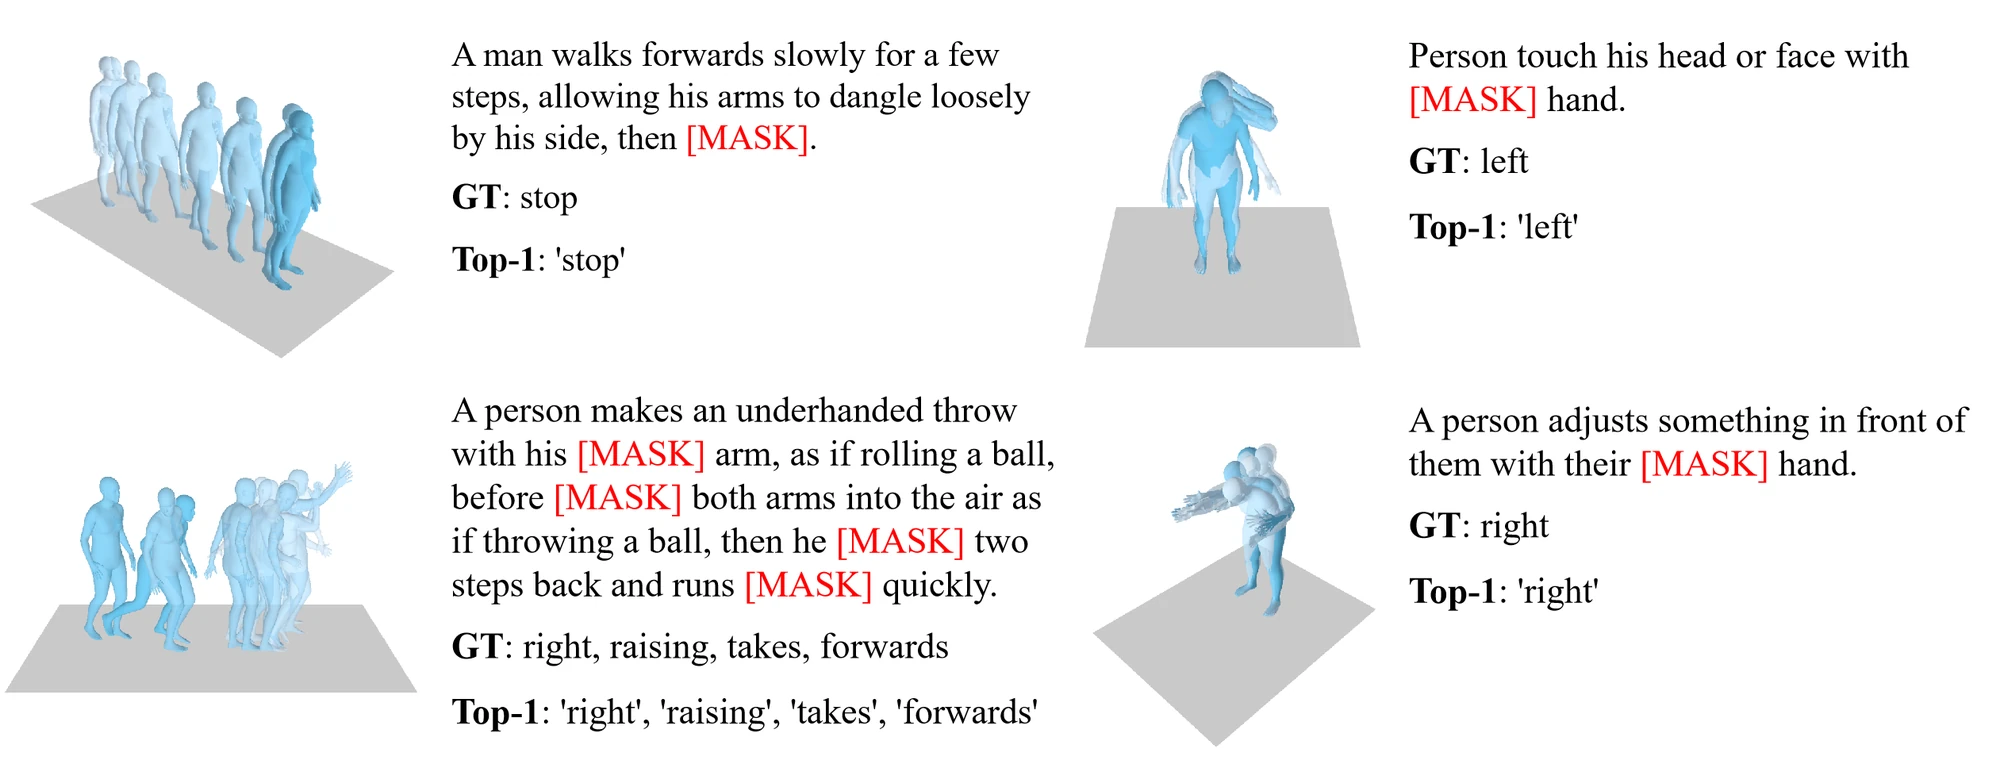
A lightweight decoder recovers masked keywords from the reasoning latent alone, including body parts (“left”, “right”) and actions (“stop”, “raising”). The plan carries semantic intent, not just compressed kinematics.
Qualitative results
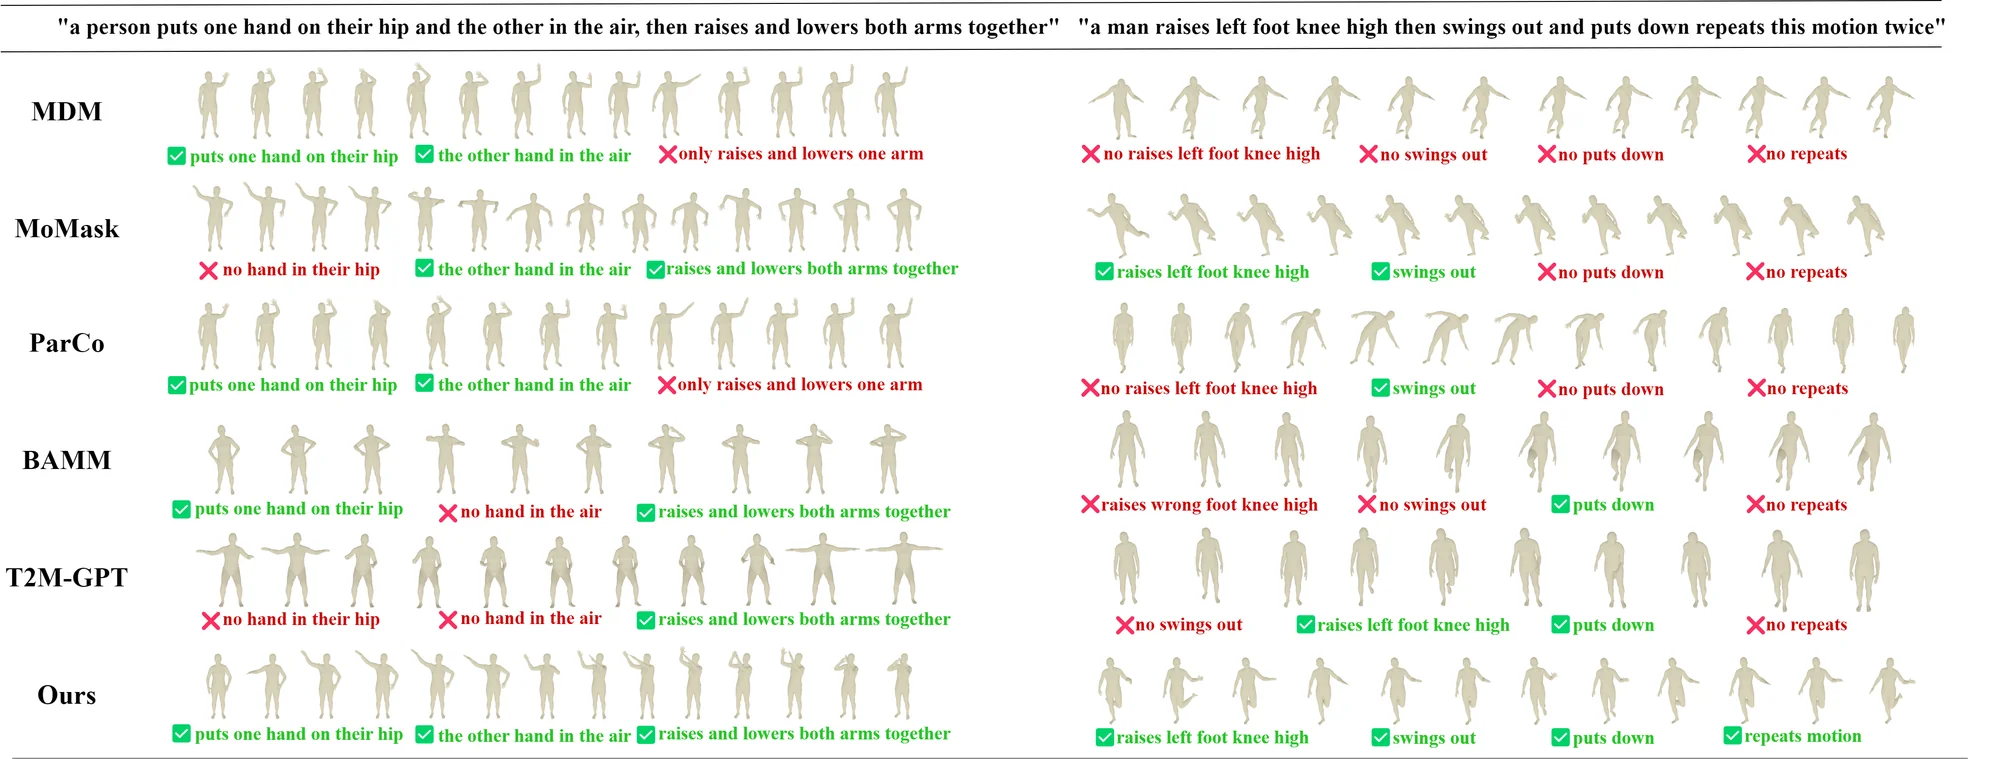
Baselines often drop concurrent actions or repetitions. Because LMR fixes the global topology first, it keeps the compositional constraints of the prompt.
“a man jumps once and then wobbles a little while moving legs apart.”
✗ Keeps jumping; no wobble.
✓ Jumps once, then wobbles.
“a man raises left foot knee high then swings out and puts down repaets this motion twice.”
✗ Misses the knee raise; no swing out, no repetition.
✗ Raises the knee but misses the swing, put-down and repetition.
✗ No knee raise, no swing out, no repetition.
✓ Knee raise, swing, put-down, repeated twice.
“a person puts one hand on their hip and the other in the air, then raises and lowers both arms together.”
✗ Reaches the initial pose but never raises and lowers both arms together.
✗ Initial pose and arm lowering, but misses the simultaneous raise.
✗ Reaches the initial pose but never raises and lowers both arms together.
✓ Initial pose, then both arms raised and lowered together.
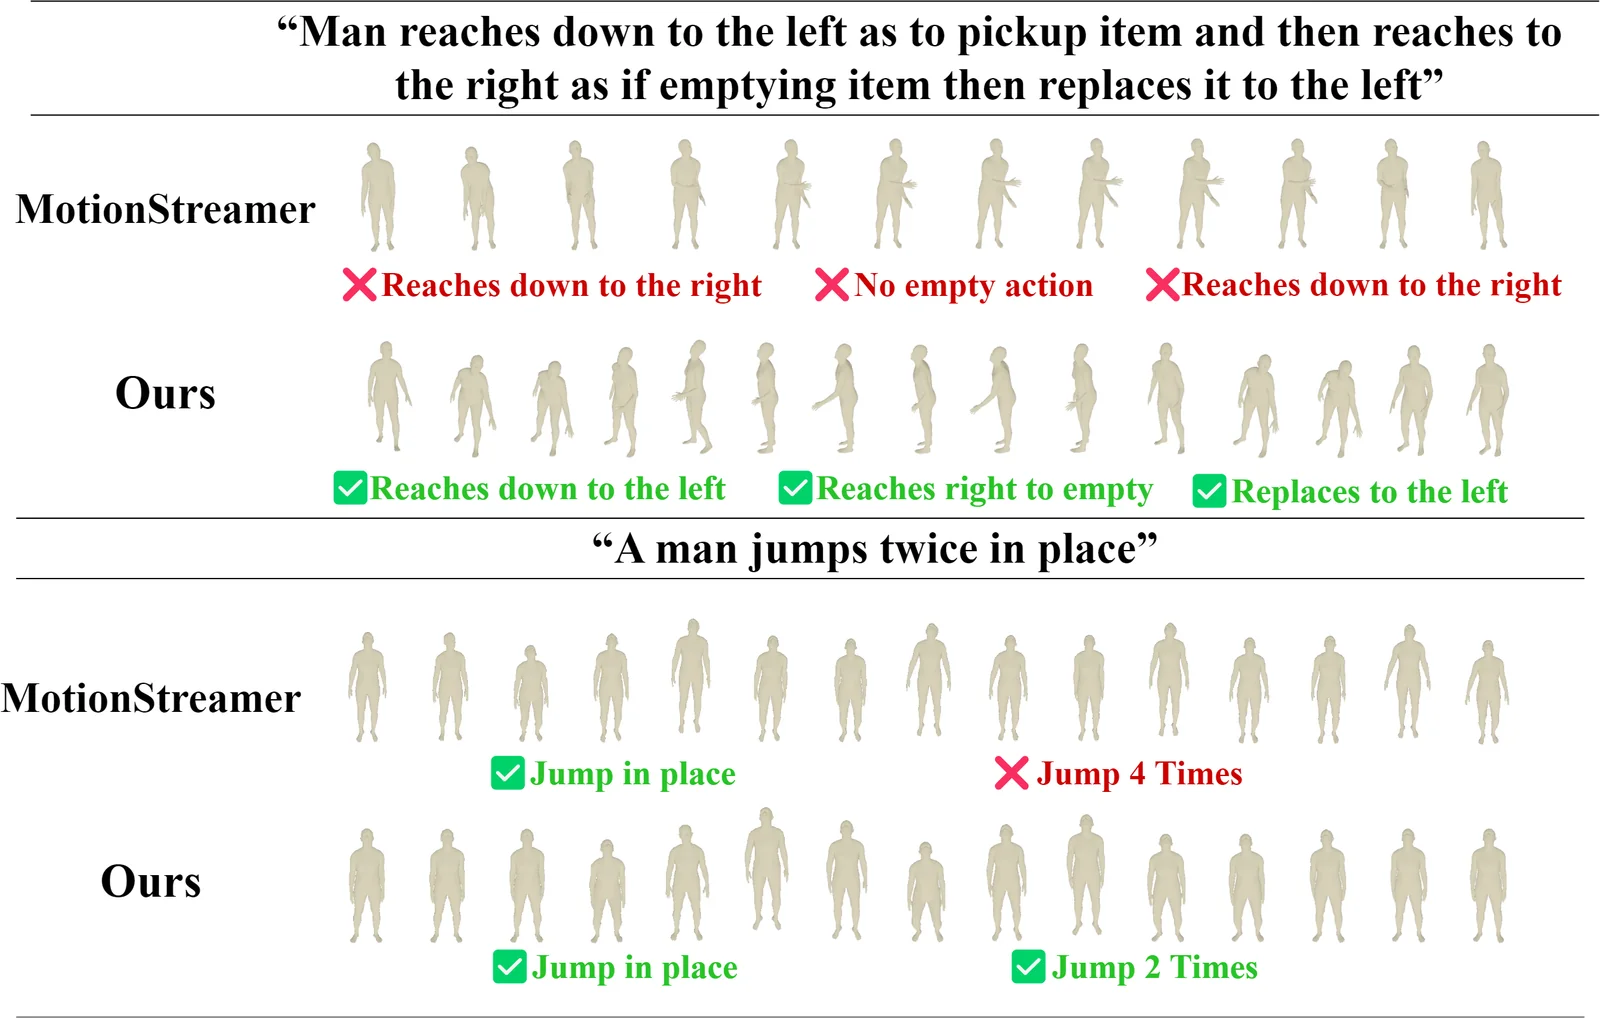
In a continuous latent space, LMR enforces logic-driven requirements such as directions, action order and repetition counts, whereas MotionStreamer often drifts from the causal logic of the prompt.
Distinguishing left from right and grounding body parts to the correct limb.
“a man kicks with his left leg.”
✗ Incorrect
✓ Correct
Distinguishing left from right and grounding body parts to the correct limb.
“a man side steps to the left.”
✗ Incorrect
✓ Correct
Following multi-clause instructions with sequential actions and spatial references.
“man reaches down to the left → reaches to the right → replaces to the left.”
✗ Breaks the sequential pattern
✓ Left → right → left
Respecting numeric constraints such as “once” and “twice”. These clips play once so the count is unambiguous.
“a person does a small jump.”
✗ Multiple jumps
✓ Exactly one jump
Respecting numeric constraints such as “once” and “twice”. These clips play once so the count is unambiguous.
“man jumps twice in place.”
✗ Wrong number of jumps
✓ Exactly two jumps
Respecting numeric constraints such as “once” and “twice”. These clips play once so the count is unambiguous.
“a person jumps up and down once.”
✗ Multiple jumps
✓ Exactly one jump
Quantitative results
On the T2M-GPT backbone, LMR lowers FID from 0.141 to 0.040 and raises Top-1 R-Precision from 0.492 to 0.537. Motion Anything scores higher on HumanML3D through multi-step bidirectional refinement; LMR keeps causal, streaming-capable autoregressive generation with KV caching.
| Method | R-Precision ↑ | FID ↓ | MM-Dist ↓ | Diversity → | ||
|---|---|---|---|---|---|---|
| Top-1 | Top-2 | Top-3 | ||||
| Ground truth | 0.511±.003 | 0.703±.003 | 0.797±.002 | 0.002±.000 | 2.974±.008 | 9.503±.065 |
| Diffusion | ||||||
| MDM | – | – | 0.611±.007 | 0.544±.044 | 5.566±.027 | 9.559±.086 |
| MLD | 0.481±.003 | 0.673±.003 | 0.772±.002 | 0.473±.013 | 3.196±.010 | 9.724±.082 |
| MotionDiffuse | 0.491±.001 | 0.681±.001 | 0.782±.001 | 0.630±.001 | 3.113±.001 | 9.410±.049 |
| FG-T2M++ | 0.513±.002 | 0.702±.002 | 0.801±.003 | 0.089±.004 | 2.925±.007 | 9.223±.114 |
| Masked (BERT-type) | ||||||
| MMM | 0.504±.003 | 0.696±.003 | 0.794±.004 | 0.080±.004 | 2.998±.007 | 9.411±.058 |
| MoMask | 0.521±.002 | 0.713±.002 | 0.807±.002 | 0.045±.002 | 2.958±.008 | – |
| BAMM | 0.525±.002 | 0.720±.003 | 0.814±.003 | 0.055±.002 | 2.919±.008 | 9.717±.089 |
| Motion Anything | 0.546±.003 | 0.735±.002 | 0.829±.002 | 0.028±.005 | 2.859±.010 | 9.521±.083 |
| Autoregressive (GPT-type) | ||||||
| MotionGPT | 0.492±.003 | 0.681±.003 | 0.778±.002 | 0.232±.008 | 3.096±.009 | 9.528±.071 |
| ParCo | 0.515±.003 | 0.706±.003 | 0.801±.002 | 0.109±.005 | 2.927±.008 | 9.576±.088 |
| MOGO† | 0.515±.003 | 0.709±.003 | 0.801±.003 | 0.064±.002 | 2.951±.008 | – |
| T2M-GPT | 0.492±.003 | 0.679±.002 | 0.775±.002 | 0.141±.005 | 3.121±.009 | 9.761±.151 |
| LMR (ours, T2M-GPT backbone) | 0.537±.005 | 0.721±.004 | 0.810±.005 | 0.040±.002 | 2.895±.017 | 9.668±.077 |
± is the 95% confidence interval. Among masked and GPT-type methods, bold is the best and underline the second best. †MOGO is reported without its post-hoc Text-Condition-Alignment module, for a fair single-pass comparison.
On KIT-ML, LMR is the best method on R-Precision and MM-Dist and cuts T2M-GPT's FID from 0.514 to 0.181; Motion Anything has the lowest FID.
| Method | R-Precision ↑ | FID ↓ | MM-Dist ↓ | Diversity → | ||
|---|---|---|---|---|---|---|
| Top-1 | Top-2 | Top-3 | ||||
| Ground truth | 0.424±.005 | 0.649±.006 | 0.779±.006 | 0.031±.004 | 2.788±.012 | 11.080±.097 |
| Diffusion | ||||||
| MDM | – | – | 0.396±.004 | 0.497±.021 | 9.191±.022 | 10.847±.109 |
| MLD | 0.390±.008 | 0.609±.008 | 0.734±.007 | 0.404±.027 | 3.204±.027 | 10.80±.117 |
| MotionDiffuse | 0.417±.004 | 0.621±.004 | 0.739±.004 | 1.954±.062 | 2.958±.005 | 11.10±.143 |
| FG-T2M++ | 0.442±.006 | 0.657±.005 | 0.781±.004 | 0.135±.004 | 2.696±.011 | 10.99±.105 |
| Masked (BERT-type) | ||||||
| MMM | 0.381±.005 | 0.590±.006 | 0.718±.005 | 0.429±.019 | 3.146±.019 | 10.633±.097 |
| MoMask | 0.433±.007 | 0.656±.005 | 0.781±.005 | 0.204±.011 | 2.779±.022 | – |
| BAMM | 0.438±.009 | 0.661±.009 | 0.788±.005 | 0.183±.013 | 2.723±.026 | 11.008±.094 |
| Motion Anything | 0.449±.007 | 0.678±.004 | 0.802±.006 | 0.131±.003 | 2.705±.024 | 10.94±.098 |
| Autoregressive (GPT-type) | ||||||
| MotionGPT | 0.366±.005 | 0.558±.004 | 0.680±.005 | 0.510±.004 | 3.527±.021 | 10.35±.084 |
| ParCo | 0.430±.004 | 0.649±.007 | 0.772±.008 | 0.453±.027 | 2.820±.028 | 10.95±.094 |
| MOGO† | 0.420±.007 | 0.634±.007 | 0.754±.007 | 0.313±.016 | 2.957±.029 | – |
| T2M-GPT | 0.416±.006 | 0.627±.006 | 0.745±.006 | 0.514±.029 | 3.007±.023 | 10.921±.108 |
| LMR (ours, T2M-GPT backbone) | 0.483±.012 | 0.701±.007 | 0.811±.006 | 0.181±.006 | 2.636±.014 | 11.032±.128 |
± is the 95% confidence interval. Among masked and GPT-type methods, bold is the best and underline the second best. †MOGO is reported without its post-hoc Text-Condition-Alignment module, for a fair single-pass comparison.
With the continuous 272-dimensional SMPL representation of MotionStreamer, LMR reaches the lowest FID (11.790 → 9.937) and the best R-Precision on HumanML3D.
| Method | R-Precision ↑ | FID ↓ | MM-Dist ↓ | Diversity → | ||
|---|---|---|---|---|---|---|
| Top-1 | Top-2 | Top-3 | ||||
| Real motion | 0.702 | 0.864 | 0.914 | 0.002 | 15.151 | 27.492 |
| T2M-GPT | 0.606 | 0.774 | 0.838 | 12.475 | 16.812 | 27.275 |
| MotionGPT | 0.456 | 0.598 | 0.628 | 14.375 | 17.892 | 27.114 |
| MoMask | 0.621 | 0.784 | 0.846 | 12.232 | 16.138 | 27.127 |
| AttT2M | 0.592 | 0.765 | 0.834 | 15.428 | 15.726 | 26.674 |
| MotionStreamer | 0.631 | 0.802 | 0.859 | 11.790 | 16.081 | 27.284 |
| LMR (ours, MotionStreamer backbone) | 0.644 | 0.812 | 0.869 | 9.937 | 15.968 | 27.373 |
HumanML3D test set, continuous motion representation. Real motion is the upper-bound reference. Among generated methods, bold is the best and underline the second best.
FID measures fidelity at the distribution level. At the level of individual sequences, LMR also beats MLD, MoMask and T2M-GPT on foot contact and ground penetration, and closely matches real motion.
| Method | FID ↓ | PFC ↓ | Float ↓ | Foot-contact ↓ |
|---|---|---|---|---|
| Real motion | 0.002 | 0.425 | 0.0212 | 0.0630 |
| MLD | 0.473 | 0.802 | 0.0304 | 0.0640 |
| MoMask | 0.045 | 0.685 | 0.0278 | 0.0683 |
| T2M-GPT | 0.141 | 0.545 | 0.0231 | 0.0663 |
| LMR (ours) | 0.040 | 0.523 | 0.0214 | 0.0632 |
All methods use official weights and the same single-inference protocol. PFC penalizes center-of-mass acceleration while both feet move; Float is the average hovering height of the lowest mesh point; Foot-contact is Float plus ground penetration.
LMR adds a small reasoning head to the tokenizer. Its generator supports KV caching, which brings inference to 0.4 ms per frame; ParCo and MoMask do not support KV caching.
| Method | Inference (ms/frame) | Training (h) | Size (M) | |||
|---|---|---|---|---|---|---|
| Tok. | Gen. | Tok. | Gen. | Tok. | Gen. | |
| T2M-GPT | 1.1 | 31 | 15 | 40 | 19.44 | 228.42 |
| ParCo | 1.2 | 5 | 4 | 18 | 6.35 | 19.44 |
| MoMask | 2.8 | 15 | 18 | 4 | 25.41 | 166.05 |
| LMR (ours) | 2.4 | 30 | 5 | 19 | 24.79 | 229.62 |
| LMR (ours) + KV cache | – | 0.4 | – | – | – | – |
Tok. and Gen. denote the tokenizer and the generator.
38 participants compared pairs of clips generated from the same HumanML3D test prompts (40 motions per comparison). For each pair they chose the motion that looks more like a real human, and the one that better matches the text; attention checks were inserted at random. LMR is preferred over every baseline and is chosen about 40% of the time even against ground truth.
The dashed line marks 50%, i.e. no preference.
Ablation
We keep the backbone and the full-rate execution tokens fixed and swap the learned reasoning tokens for other guidance signals. Language-side guidance, either full CLIP token sequences or a Motion-R1-style textual chain-of-thought, improves retrieval but leaves FID high: text is too sparse to steer high-frequency motion. A coarse-to-fine baseline that stays in the kinematic space accumulates errors.
“a person puts one hand on their hip and the other in the air, then raises and lowers both arms together.”
✗ Semantic error: stretches the waist left and right instead.
✗ Never raises and lowers both arms together.
✗ Semantic error: stretches the waist left and right instead.
✗ Never raises and lowers both arms together.
✓ Performs every action correctly.
| Guidance | FID ↓ | R-Precision ↑ | MM-Dist ↓ | Diversity → | ||
|---|---|---|---|---|---|---|
| Top-1 | Top-2 | Top-3 | ||||
| Baseline (no guidance) | 0.242 | 0.497 | 0.684 | 0.778 | 3.148 | 9.914 |
| + TMR embeddings | 0.120 | 0.472 | 0.666 | 0.759 | 3.210 | 9.965 |
| + Coarse-to-fine AR | 0.154 | 0.488 | 0.679 | 0.779 | 3.097 | 9.692 |
| + CLIP tokens (L = 77) | 0.206 | 0.523 | 0.718 | 0.812 | 2.963 | 9.719 |
| + Explicit language CoT | 0.188 | 0.511 | 0.702 | 0.795 | 3.021 | 9.752 |
| + Reasoning tokens (ours) | 0.040 | 0.537 | 0.721 | 0.810 | 2.895 | 9.668 |
T2M-GPT backbone on HumanML3D; all variants use full-rate (1×) execution tokens.
To rule out extra tokens, parameters or prefix capacity, we keep all of them fixed and perturb only the content of the reasoning tokens before regenerating the execution stream.
With random or shuffled but still valid codes, FID barely changes while Top-1 R-Precision drops from 0.537 to 0.493 and 0.497: the motion quietly decouples from the text and drifts toward generic, distribution-typical actions, which FID does not penalize. Erasing the content with constant or zero codes makes FID about 4.7× worse. The only variable is the reasoning content, so the improvement is caused by it.
| Reasoning-token content | FID ↓ | Top-1 ↑ | MM-Dist ↓ |
|---|---|---|---|
| Original | 0.040 | 0.537 | 2.895 |
| Random valid codes | 0.031 | 0.493 | 3.110 |
| Shuffled order | 0.038 | 0.497 | 3.073 |
| Constant (all codes 0) | 0.183 | 0.460 | 3.349 |
| Zeroed embedding | 0.184 | 0.446 | 3.351 |
Ablations
Unless noted, ablations use the discrete T2M-GPT backbone on HumanML3D.
Execution tokens stay at full rate because reconstruction upper-bounds generation (MPJPE 16.608 at 1× vs. 30.294 at 1/4×). For reasoning tokens, 1/4× is the knee point: 1/2× stays too close to the execution stream, and 1/8× over-compresses and loses the order of sub-actions. A single joint sequence fails at both.
| Method | Token scale | Execution quality | Reasoning alignment | Generation | ||||
|---|---|---|---|---|---|---|---|---|
| Exec. | Reas. | rFID ↓ | MPJPE ↓ | R1 ↑ | ACC ↑ | gFID ↓ | MM-Dist ↓ | |
| Single sequence | 1/4 | – | 0.095 | 30.294 | – | – | 0.137 | 3.225 |
| Single sequence | 1 | – | 0.044 | 16.608 | – | – | 0.242 | 3.148 |
| Single sequence (joint) | 1 (joint) | 0.083 | 22.512 | 0.429 | 0.463 | 0.354 | 3.253 | |
| Dual (ours) | 1 | 1/2 | 0.044 | 16.608 | 0.466 | 0.536 | 0.212 | 3.250 |
| Dual (ours) | 1 | 1/4 | 0.044 | 16.608 | 0.474 | 0.538 | 0.040 | 2.895 |
| Dual (ours) | 1 | 1/8 | 0.044 | 16.608 | 0.462 | 0.533 | 0.062 | 3.145 |
| Dual (ours) | 1/2 | 1/8 | 0.094 | 24.790 | 0.468 | 0.526 | 0.069 | 3.182 |
| Dual (ours) | 1/2 | 1/16 | 0.094 | 24.790 | 0.455 | 0.519 | 0.076 | 2.969 |
| Dual (ours) | 1/4 | 1/16 | 0.095 | 30.294 | 0.463 | 0.533 | 0.105 | 3.092 |
Exec. and Reas. are token-sequence length ratios T/Tm. The joint setting uses one sequence for both roles. The highlighted row is the configuration used in the paper.
“a person briefly strums a guitar.”
Details are well restored, close to GT.
Flickering at the beginning; slight swing in the left hand.
The right hand's string plucking is lost.
“a person doing a spesific moves with legs and hands while doing boxing.”
Training the execution branch first and then freezing it works best. End-to-end training lets the semantic objectives degrade reconstruction, fine-tuning drifts the execution space, and independent networks lose the shared kinematic grounding.
| Training strategy | Execution quality | Reasoning alignment | Generation | |||
|---|---|---|---|---|---|---|
| rFID ↓ | MPJPE ↓ | R1 ↑ | ACC ↑ | gFID ↓ | MM-Dist ↓ | |
| End-to-end (joint) | 0.133 | 22.563 | 0.499 | 0.519 | 0.145 | 3.174 |
| Two-stage, freeze (ours) | 0.044 | 16.608 | 0.474 | 0.538 | 0.040 | 2.895 |
| Two-stage, fine-tune | 0.101 | 20.276 | 0.481 | 0.549 | 0.109 | 3.077 |
| Independent networks | 0.044 | 16.608 | 0.489 | 0.556 | 0.097 | 3.134 |
Lalign gives global alignment but no local detail (ACC 0.000); Lmtp gives local detail but loses global coherence (R1 0.036). Together they give the best generation.
| Reasoning objective | Reasoning alignment | Generation quality | ||
|---|---|---|---|---|
| R1 ↑ | ACC ↑ | FID ↓ | MM-Dist ↓ | |
| Lalign | 0.482 | 0.000 | 0.136 | 3.189 |
| Lmtp | 0.036 | 0.534 | 0.120 | 3.161 |
| Lalign + Lmtp (ours) | 0.474 | 0.538 | 0.040 | 2.895 |
Against the best single-granularity tokenizer, the dual strategy improves FID from 0.137 to 0.040 on T2M-GPT and from 11.790 to 9.937 on MotionStreamer. The gain is larger in the discrete space, where quantization makes tokens semantically sparse.
| Tokenizer | Downsampling | FID ↓ | R-Precision ↑ | MM-Dist ↓ | Diversity → | ||
|---|---|---|---|---|---|---|---|
| Top-1 | Top-2 | Top-3 | |||||
| Continuous latent space | |||||||
| MotionStreamer | 2× | 21.836 | 0.449 | 0.606 | 0.684 | 18.524 | 27.008 |
| MotionStreamer | 4× | 11.790 | 0.631 | 0.802 | 0.859 | 16.081 | 27.284 |
| LMR (ours) | Dual | 9.937 | 0.644 | 0.812 | 0.869 | 15.968 | 27.373 |
| Discrete latent space | |||||||
| T2M-GPT | 1× | 0.242 | 0.497 | 0.684 | 0.778 | 3.148 | 9.914 |
| T2M-GPT | 4× | 0.137 | 0.482 | 0.667 | 0.763 | 3.359 | 9.758 |
| LMR (ours) | Dual | 0.040 | 0.537 | 0.721 | 0.810 | 2.895 | 9.668 |
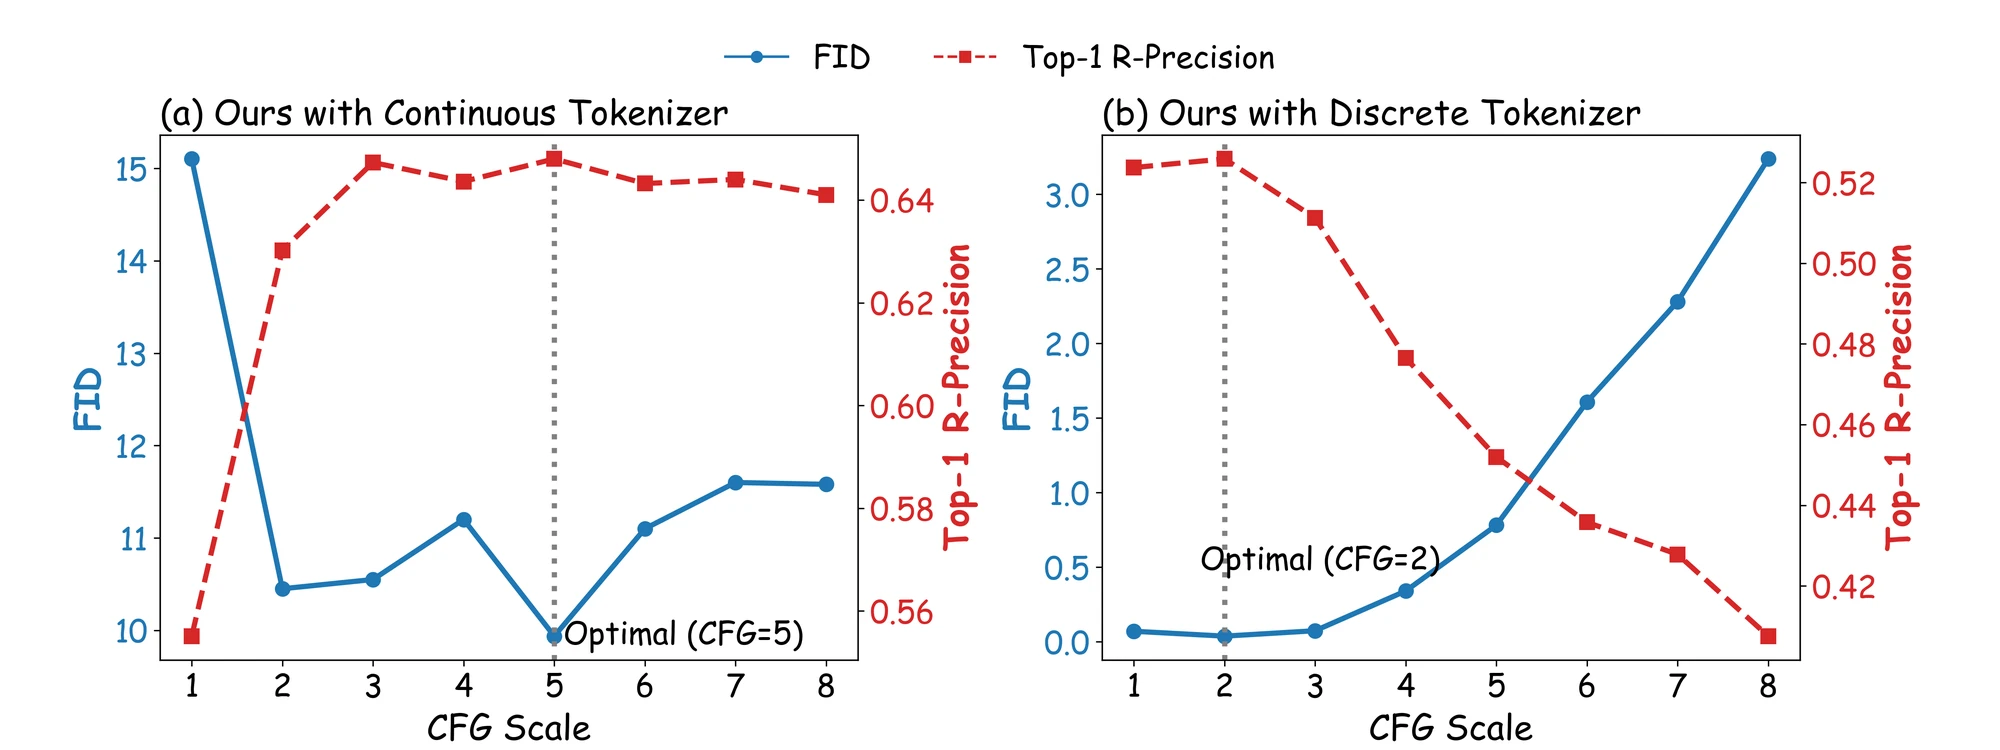
The continuous backbone performs best at a classifier-free guidance scale of 5; the discrete backbone peaks at 2 and degrades quickly with stronger guidance.
Performance varies smoothly with the loss weighting λalign : λmtp and the reasoning codebook size, with a single clear optimum at 0.5 : 0.1 and 512.
| Hyper-parameter | Setting | FID ↓ | Top-1 ↑ | MM-Dist ↓ |
|---|---|---|---|---|
| λalign : λmtp | 0.5 : 0.05 | 0.088 | 0.511 | 3.048 |
| 0.5 : 0.1 (main) | 0.040 | 0.537 | 2.895 | |
| 0.5 : 0.2 | 0.075 | 0.505 | 3.063 | |
| Reasoning codebook size | 256 | 0.072 | 0.510 | 3.047 |
| 512 (main) | 0.040 | 0.537 | 2.895 | |
| 1024 | 0.071 | 0.518 | 3.012 |
Gallery
LMR keeps the causal, autoregressive generation of its backbone, so it can produce long motions in a streaming fashion.
Three samples for the same prompt: “a person walks in a circle.”
@article{qian2026think,
title = {Think Before You Move: Latent Motion Reasoning for Text-to-Motion Generation},
author = {Qian, Yijie and Wang, Juncheng and Feng, Yuxiang and Xu, Chao and Lu, Wang and
Liu, Yang and Sun, Baigui and Chen, Yiqiang and Liu, Yong and Wang, Shujun},
journal = {IEEE Transactions on Pattern Analysis and Machine Intelligence},
year = {2026}
}